 Login AI
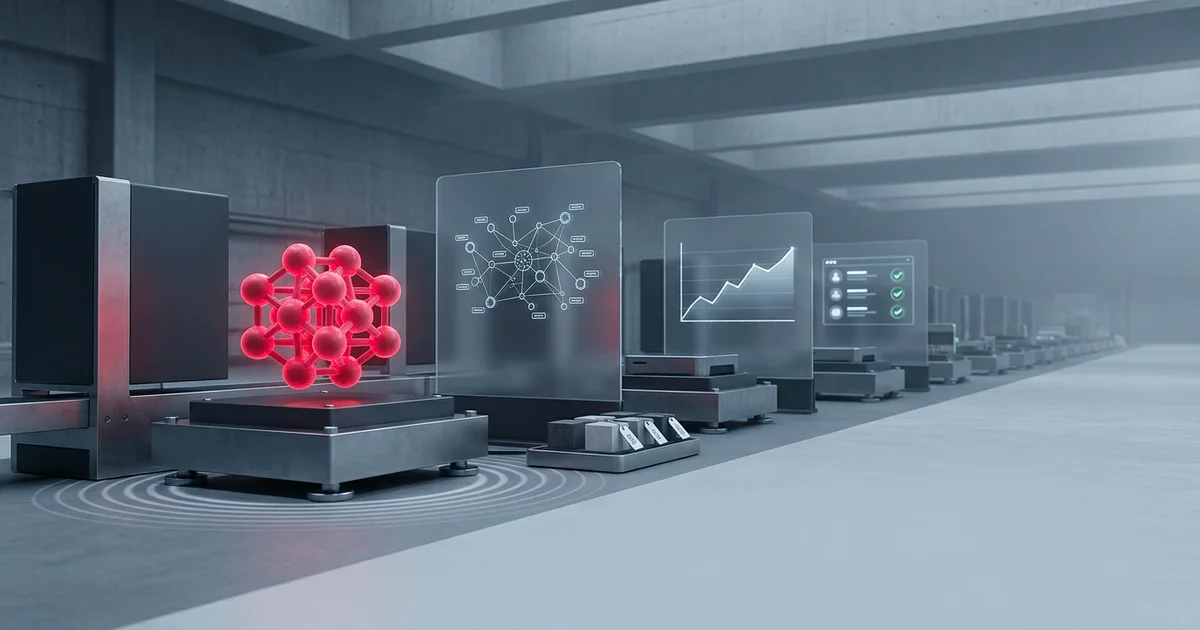
Synthetic data for model training
We build synthetic data generators for model training: rare classes, privacy, augmentation, and validation against a real holdout.
The generator adds rare cases, and the model is checked on real data.
Pricing
from ₽500,000
per project
This is the lower bound of a project. We scope the exact quote after a brief: it depends on volume and the number of integrations.
Capabilities
Rare-case generation
We build rare classes and borderline combinations by rule: the generator adds cases your dataset holds in single digits and keeps the links between features.
Privacy inside the perimeter
We de-identify records and train the generator in a closed environment: source rows stay in local storage, and only synthetic rows leave.
Validation on a real holdout
We keep 10-15% of real rows aside and measure precision, recall, and rare-class share: the report shows the synthetic contribution per class.
Dataset augmentation
We add synthetic rows to the real set: we balance classes, add gaps and noise, and preserve field types and business rules.
From request to result
1
Data audit
We inspect real rows, rare classes, and privacy limits: we count distributions, gaps, and links between fields.
2
Generator design
We pick the generator model and mixing rules: we fix the field schema, types, and target holdout metrics.
3
Generation and validation
We generate the set, compare distributions, and measure precision and recall on held-out real rows.
4
Pilot and handover
We run the generator in your environment, hand over the config and report, and train your team to repeat the cycle.
Check if it fits you
Good fit
Rare classes
Your dataset has hundreds of rows and you need thousands: the generator adds rare cases and balances classes.
A real holdout exists
You have 10-15% of held-out rows for checks: synthetic quality is confirmed on live data.
Not a fit
No real rows at all
The generator leans on real distributions: you need a starter sample of at least a few hundred rows.
Regulated decisions without validation
Credit and medical decisions need a holdout and a responsible sign-off: synthetic data without a check does not fit here.
What you get
10,000
Rows in the base set
The starter set holds 10,000 tabular rows, so the model sees rare feature combinations before you collect more real cases.
tables
Tables as the base modality
Tables cover the starter scenario: the generator builds rows with features, types, and gaps, then scales to text and images.
privacy review
Privacy review on request
A privacy review adds a recovery-attack test and a data-flow map, and your security team signs off before the first generated batch.
What the delivery includes
A generator
A generator with a config, mixing rules, and launch scripts: you reproduce the set with one command and change parameters for a new product.
A synthetic dataset
A synthetic dataset in tabular format with field descriptions, limits, and links: 10,000 rows start training, and the volume grows with your task.
A validation report
A validation report with holdout metrics: precision, recall, and a confusion matrix per class, plus a side-by-side with training on the source sample.
How the system is built
Fitting to real data
We fit the generator to real data: we count distributions, correlations, and rare combinations in your sample, then fix the feature schema and the validation rules.
Rare-case generation
The generator creates rare classes by set rules: it mixes features, adds noise, and builds combinations that appear fewer than a hundred times in the source sample while keeping field links intact.
A check on a real holdout
We check every generated set on a real holdout: we count precision and recall per rare class, compare distributions, and deliver a report with metrics before and after the synthetic rows.
Where the solution pushes back
- 01
Synthetic fidelity
Synthetic rows follow the real distribution to within 2-3% on key features, and rare combinations need separate calibration for every new product.
- 02
Pseudonymization and reconstruction checks
We pseudonymize rows with k-anonymity and test reconstruction attacks: this adds two weeks to the launch, and the generator runs on your hardware.
- 03
Validation on a real holdout
Validation runs on a real holdout: the model trains on synthetic rows, and you confirm the metric on the held-out 10-15% of real rows.
Technologies
The technologies we use in our work and their role in a project.
Generation and storage
We write generators in Python, train on PyTorch, store rows and metadata in PostgreSQL, keep artifacts in MinIO, and run and scale jobs on Kubernetes.
Cost calculator
This is an indicative range, not a quote. We scope the exact estimate after a brief: it depends on volume and the number of integrations.
Modality
Rows
Privacy review
Validation
Add-ons
Support
Year one: updates and monitoring, a reply within 2 business days.
Service
Synthetic data for model training
The estimate covers our team's work. Hardware, third-party service licences and travel are added on request.
Estimated cost
₽550,000
Timeline
3 wk
Frequently asked questions
Why use synthetic data when real data exists?
Synthetic data covers rare classes and private scenarios: a rare defect may have ten real rows, and the generator produces thousands of consistent examples. Training mixes both sets.
How do you protect privacy?
We de-identify records, train the generator in a closed environment, and test recovery attacks. Source rows stay in local storage, and synthetic rows pass a closeness check against real records.
What formats do you deliver?
Tables come as CSV and Parquet, text as JSONL, images as PNG with JSON labels. We fix the field schema and types in the generator contract.
How long does the launch take?
A pilot takes two to four weeks: data audit, generator design, generation, and a holdout check. Config handover and team training are part of the term.
What teams add to this service
Related Services
Part of Solutions
Implementation Examples
−90%
Escaped defects
Ready to discuss your task?
Leave a request – we'll get back with a proposal and a preliminary estimate.
Contact us